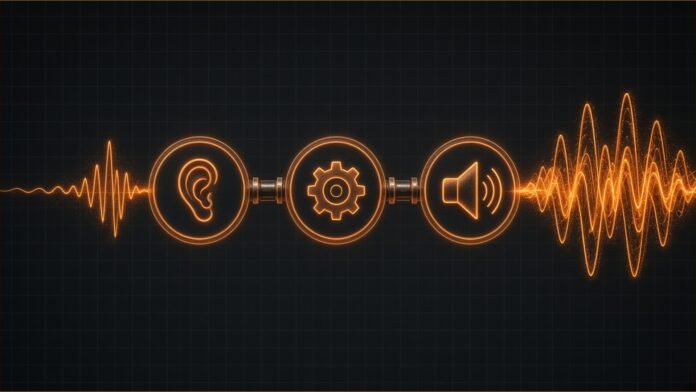
Mistral AI has released Voxtral 3, described in its announcement on 20 October 2026 as “a new family of state-of-the-art speech-to-text and text-to-speech models, alongside a voice agent SDK”. The Paris-based company says the release brings listening, reasoning, tool calling and speaking into “a single real-time streaming pipeline”.
The launch takes Mistral directly into the voice agent market, where OpenAI, ElevenLabs, Deepgram and Google already compete. Mistral’s pitch rests on price and sovereignty: the models are available through its API or for self-deployment, so organisations can control where audio is processed and whether it is kept. The benchmark claims in the announcement are Mistral’s own.
In brief
- Mistral has launched Voxtral 3 transcription and text-to-speech models plus a voice agent SDK built on LiveKit.
- Transcription covers 50 languages, “including 24 official EU languages”; speech output supports “35+ languages and 50+ dialects”, Mistral says.
- Mistral claims its Small transcription model outperforms Whisper, Scribe v2 and Gemini 3.5 Transcribe; these comparisons and its TTS evaluations are the company’s own.
Listening: transcription in 50 languages
Mistral says Voxtral Transcribe 3 expands support to 50 languages, including many low-resource Asian and Indic languages. The models identify who said what (diarisation), use supplied keyphrases to improve accuracy (context biasing) and detect when a speaker has finished.
According to Mistral, the Small version “achieves state-of-the-art results across diarization and multilingual transcription, including in English, French and Spanish. It outperforms Whisper, Scribe v2 and Gemini 3.5 Transcribe.” Those results come from Mistral’s charts on public benchmarks such as FLEURS and an Artificial Analysis word error rate index, as presented by Mistral. The smaller Mini variant “is 4B parameters”.
A realtime model, Voxtral Realtime Transcribe 3, is built for agents. Mistral says it delivers transcription “at sub-500ms latency in over 35 languages”, although the product card on the same page says “40+ languages”.
Speaking: expressive voices and Pro Voice
The text-to-speech model, Voxtral Mini TTS 3, adjusts emotion, pace and emphasis based on context, according to Mistral. Developers can also give explicit instructions for emotion, pacing and emphasis. Voice presets are available in 18 languages.
Pro Voice, aimed at professional use, can reproduce a speaker’s character, emotional range and style across languages “using just 30 minutes of audio”, Mistral says.
Mistral claims its speech model “costs less to run than comparable models from OpenAI TTS-1, Deepgram, ElevenLabs Flash and Gemini Flash.” Its quality-per-dollar charts lean on its own testing. Three of the four, on pronunciation control, multilingual speech and expressive English, are labelled “Internal eval”, and all four use gemini-3.8-flash as the judge. One uses Voice Code Bench from BeSimple AI.
The voice agent SDK
The SDK is “built on LiveKit” and runs speech in, reasoning and speech out as one streaming pipeline. The realtime transcription model listens, a general model such as Mistral Small reasons and calls tools, and Voxtral Speech 3 replies. Because no stage waits for the one before it, Mistral says, “each turn completes in under one second”, and the agent stops talking when the caller interrupts.
Agents can verify identities, check bills or book appointments using function calling, web search and retrieval, Mistral says. They work over SIP telephony and WebRTC, and each stage can be swapped independently.
Pricing and availability
Voxtral 3 is available now through the Mistral API, via European, US and global endpoints, or for self-deployment.
| Model | Price |
|---|---|
| Voxtral Mini Transcribe 3 (batch) | $0.0035/min |
| Voxtral Mini Transcribe Realtime 3 | $0.008/min |
| Voxtral Small Transcribe 3 | $0.0040/min |
| Voxtral Speech 3 (batch and realtime) | $13 per 1M characters |
Our read
Mistral is offering a full voice stack at aggressive prices, with the option to keep audio in-house, which is a strong pitch for European contact centres and regulated industries. But nearly every performance claim comes from Mistral’s own charts, and several speech evaluations are internal and judged by another AI model. Independent tests will show whether Voxtral really beats the rivals it names.
Sources
- Mistral AI: “Voxtral 3” (20 October 2026).
Related stories
- Mistral Releases Timestral, Its First Time-Series Foundation Models
- CERN and Mistral Sign Intent to Build a Large Physics Model
- Mistral Large 4 Preview: Artificial Analysis scores it 38
Follow @tsnmediahub on X for breaking AI news as it happens.
Follow on X